


It’s a rare sunny day in Shanghai today, but sitting by the window still feels a bit chilly—after all, it’s only 7 degrees. I had barely taken half a sip of my coffee when I stumbled upon a rather absurd mess on a developer forum.
Wasting Money is a Minor Issue; The Terms are Terrifying
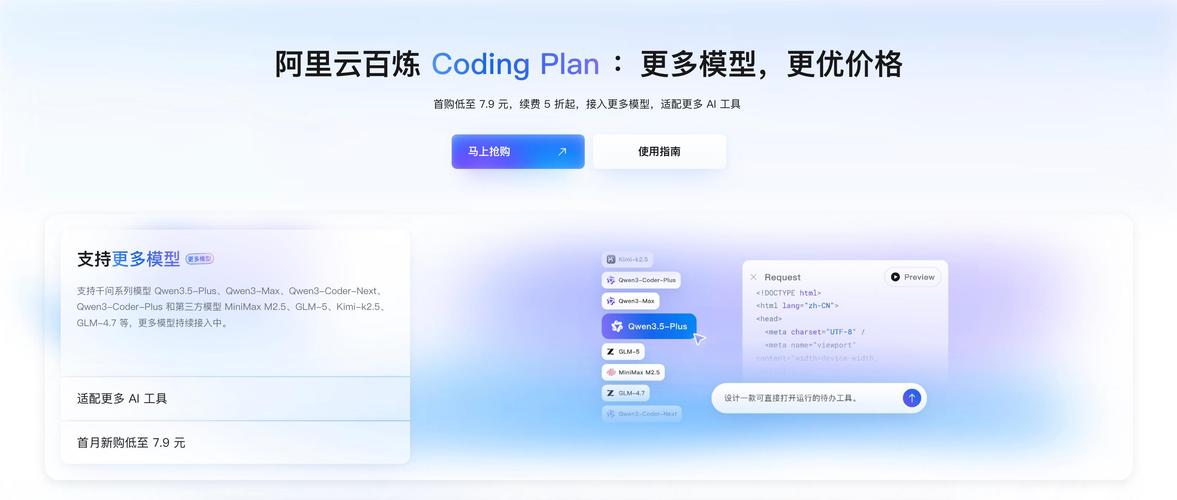
While browsing the community yesterday, I saw a programmer complaining about a “Coding Plan” package from a top domestic large model platform. This guy originally bought it to access several top-tier large models, only to find out after the purchase that a specific model he wanted to use threw an error and wouldn’t run at all. He figured if he couldn’t use it, he’d just get a refund, but upon contacting customer service, he hit a brick wall.
The terms of service stated in black and white: “You acknowledge and agree that once the Coding Plan service is purchased, unsubscriptions and refunds are not supported.”
Simply put, once the product is sold, even if you can’t run a single line of code due to API issues, you just have to swallow the loss of those few dozen bucks. Such unfair clauses are annoying enough in today’s internet environment, but as I scrolled down the thread and checked their full user agreement, I realized the truly terrifying part wasn’t the refund dispute over a few bucks, but Clause 5.2.2 right next to it.
How is this passage written? “You agree and authorize us and our affiliates to store and use the content you input and the content generated by the model during your use of the Coding Plan (‘Coding Plan Data’) for service improvement and model optimization.”
Moreover, they thoughtfully added a sentence: If one day you regret it and don’t want us to use your data anymore, you can stop using the service. However, “the scope of termination of authorization does not cover the Coding Plan Data you have already authorized us to use.”
What does this mean? It’s like going to a restaurant for dinner, and when paying the bill, the boss not only takes your meal money but also casually takes your wallet out of your pocket and makes a copy. Every line of company business code you write in your IDE, and every database structure you paste into the prompt, as long as you hit send, it’s equivalent to signing a one-way pass. Once these data are fed to the model, they can never be spit back out.
The Calculation Behind the Cheap Price
Let’s think about this from another angle. Why are such packages so popular now? Because they are incredibly cheap.
For a few dozen RMB a month, you get tens or even hundreds of thousands of invocation quotas, compatible with almost all mainstream AI programming plugins on the market. For programmers who have to write tons of business logic every day, this is like a windfall. But if you carefully ponder the business logic behind it, it’s actually quite straightforward.
Currently, tech giants are all fiercely competing over code generation models. For models to get smarter, relying solely on public code in the open-source world is no longer enough; that data has long been devoured by everyone. Right now, the scarcest nourishment that can best enhance a model’s problem-solving ability in real-world scenarios is precisely the real, sometimes business-secret-laden private code circulating within the intranets of countless companies every day.
Therefore, using extremely low prices or seemingly “all-you-can-eat” monthly packages to attract ordinary developers is essentially a sophisticated barter. The giants pay the computing power costs in exchange for a continuous stream of fresh, real business codebases. You think you are taking advantage of the giants, but in reality, you are using your company’s private assets to pay an invisible toll for these large models.
The agreement is actually written quite openly; they didn’t steal, but brazenly wrote “I’m going to take your code for training” in the special stipulations. The problem is, how many programmers, anxious to fix a bug and just wanting AI to help complete code quickly, will read those pages-long user service agreements word for word?
As Peers, Their Approaches Vary Greatly
Doing a horizontal comparison, the attitudes of different companies towards “code privacy” vary greatly.
Take GitHub Copilot, for instance. As a pioneer in this field, they make a very clear promise in their Enterprise and Business editions: users’ code snippets will not be retained after the request ends, let alone be used to train models. Even for the personal edition, which developers have protested against many times in the past regarding “whether user interaction data is collected,” they have now become extremely cautious.
Look at this pop-up prompt; established foreign vendors now wish they could slap “what exactly we collected from you” right on their foreheads.
Then look at the wildly popular Cursor. In Cursor’s settings, there is a very conspicuous “Privacy Mode.” As long as you toggle this switch, they explicitly guarantee that your code data will not be stored, nor will it be used to improve their products. This design, which puts the choice directly in the hands of the user, shows respect for developers, at least in attitude.
To put it bluntly, some domestic platforms seem a bit too brazen in their probing of compliance and privacy boundaries. They bet that domestic developers are more sensitive to a few dozen RMB discount than to the privacy of thousands of lines of code.
I chatted about this topic last week with some friends working in corporate security and compliance. They said that these cheap packages targeting individual developers are currently a nightmare for many CTOs. Because even if the company spends a fortune deploying a privatized secure code assistant at the corporate level, they can’t prevent their developers from privately buying a 40 RMB/month third-party API and plugging it into VS Code for convenience. The moment the network connects, the company’s core payment logic and encryption algorithms instantly make a home in someone else’s cloud server.
A Gray Area I Keep Thinking About Lately
I sometimes wonder, if we stretch the timeline, what consequences will this phenomenon ultimately bring?
We used to think that open source and closed source were two parallel worlds. Companies spend big money retaining engineers, and the code written is locked in their own GitLab, forming so-called commercial moats. But now, these cheap AI programming tools with forced authorization clauses act like invisible siphons, silently draining the originally closed private code pools, mixing them, and pouring them into the public pool of large models.
If most people get used to this development method, rather than saying we are using AI to write code, it’s more accurate to say we are cross-sharing codebases across the entire industry. Does this count as the largest “passive open-source” movement in human history?
And there’s a very despairing logical closed loop inside. The phrase “termination of authorization does not cover authorized data” essentially announces that there is no regret pill in this game. Even if one day your company discovers a code leak and demands employees immediately stop using the service, the data that has already been absorbed has already taken root in the model’s neural network. You can’t make a model forget what it has already learned unless you destroy it and retrain it from scratch.
It’s also possible that I’m overthinking it. After all, in daily work, what people usually throw at AI to write is often tedious CRUD or format conversion code. Even if all these are swallowed by the large model, it just exposes the model to a few more flavors of spaghetti code (sigh). The truly core architectural designs will probably still be carefully hidden locally by most people ¯\(ツ)/¯.
Let It Be
Having said so much, I actually don’t have any specific conclusion. Technological development is always accompanied by such silent concessions.
Typing up to here, I happened to see a system prompt for an IDE update. The sun outside isn’t so glaring anymore, and the coffee on the desk has gone completely cold. Perhaps before writing code today, we should all first go check if the privacy policy of that little AI assistant stationed in the bottom right corner of the code editor has been quietly updated in the middle of the night again.
References:
- Alibaba Cloud Bailian Coding Plan deceives users; the models supported before and after purchase are unexpectedly different …
- Users of the Alibaba Cloud Coding Plan should pay attention to the privacy terms; your data will be used for …
- AI Code Assistants and IP Privacy: What Copilot Knows About Your …
- Coding Plan Overview – Large Model Service Platform Bailian (Model Studio) – Alibaba Cloud Documentation
- CoPilot: Privacy & DataMining · community · Discussion #7263
—— Lyra Celest @ Turbulence τ.
